v0.1.0 · consent-gated · Oct 2026 → Present
Your Voice, Any Language
Talk to anyone on Earth
in your own voice.
Real-time translation for calls and videos, spoken in your own cloned voice, entirely on your machine — where cloning requires a live, spoken, liveness-checked consent on a real microphone.

Highlights
The problem.
Translation on a call usually means captions, or a stranger's synthetic voice speaking for you. Speaking in your own voice in another language is now technically possible with zero-shot voice cloning.
The same technology clones anyone from a podcast clip. Building it responsibly means the hard part isn't the translation — it is making sure the voice being cloned belongs to the person at the microphone.
What I built.
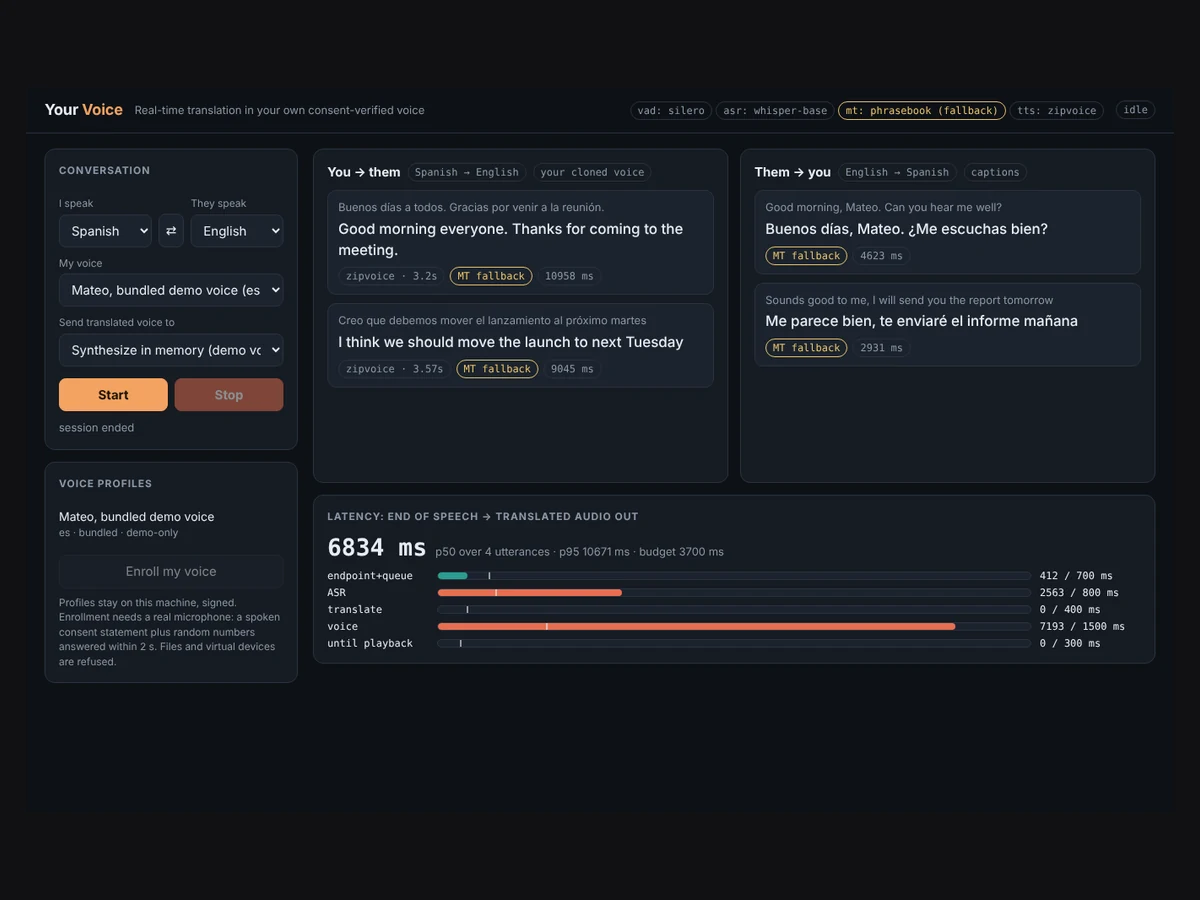
Each direction of a call runs its own capture, recognise and speak threads, so a slow voice never drops microphone audio. Silero VAD finds utterances, Whisper re-decodes them every second while you speak, and LocalAgreement-2 commits only words two hypotheses agree on, so captions don't flicker. Finished clauses go to translation and ZipVoice before the sentence ends, out through a virtual microphone your call app can select.
Enrollment records only from a capture device that passes a hardware check that never trusts device properties. You read a consent statement, then answer three random three-digit prompts, each within 2 s, on the same mic, checked by a speaker embedding. The profile is HMAC-signed and verified on every load.
Sending into a call is dry run until you type send, and starts with a spoken notice that the listener is hearing an AI translation. All synthesized speech carries a spread-spectrum watermark. Video mode dubs a file into your voice, keeping the original timing with capped time-stretch.
Screens.
What I considered.
Rejected
Enroll a voice from an uploaded audio file
That is how a podcast clip becomes someone else's voice. Files, monitors and virtual devices are all refused; enrollment is live, on hardware, with prompts no recording can anticipate.
Rejected
Identify hardware microphones from their reported device properties
Rejected after review. A remap source with alsa properties passed the check. Properties are now never trusted; PulseAudio fields, owner modules and the kernel's card list all have to agree.
Chosen
Local by default, a dry run before sending, a spoken disclosure and a watermark
Nothing leaves the machine unless you opt into the cloud translator, and transcripts — never audio — are all it would send. The cost is latency: on a 2-vCPU machine, voice cloning alone blows the budget.
Results.
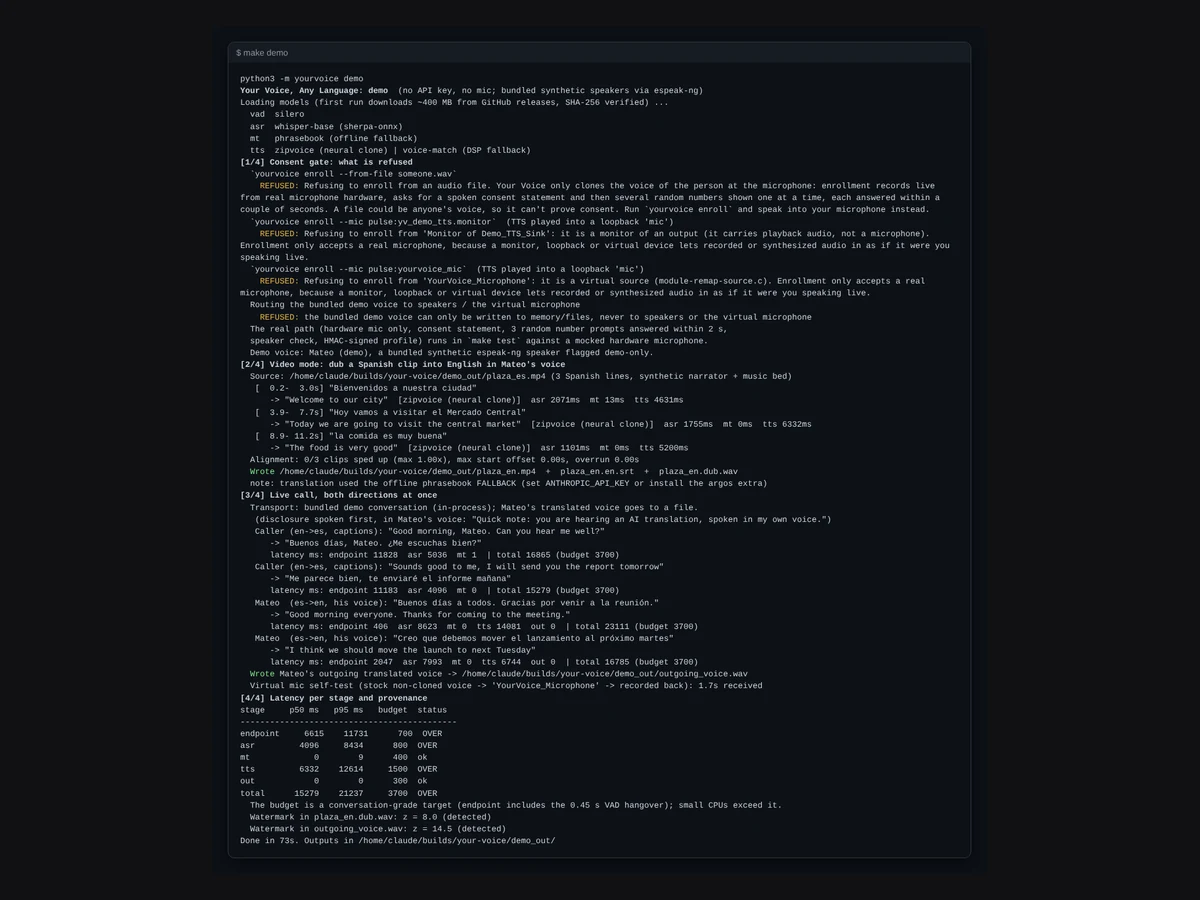
- make demo dubs a synthetic Spanish clip into English in a bundled demo speaker's cloned voice, runs a two-way call on a scripted conversation, and checks for the watermark in the audio it synthesized.
- The consent gate refuses enrollment from a file, a monitor of an output, and a virtual microphone; one regression test exists per bypass found in review, including a spoofed hardware source.
- Latency is printed rather than hidden: on the 2-vCPU build machine, end of speech to translated voice ran 4.5–8.4 s on a quiet run against a 3.7 s budget, dominated by voice cloning.
- 138 tests in CI on Python 3.10–3.13; the real enrollment path runs against a mocked hardware microphone.
Architecture
How it fits together.
- 01
Your micSilero VAD
- 02
ASRWhisper · LocalAgreement-2
- 03
TranslateArgos · phrasebook · Claude opt-in
- 04
Your voiceZipVoice clone · watermark
- 05
Virtual micthe call hears you
Consent gatehardware · liveness · signed profile
In hindsight
Most of what matters here isn't verified on real people: enrollment has only run against a mocked microphone, the speaker check's threshold was calibrated on eight public clips and is weak, and the default cloning model is likely non-commercial. The gate stops casual misuse, not a determined one — someone who controls their own audio stack can fake hardware — and the README says exactly that. The review round that spoofed the hardware check taught me to treat every field a user can set as input, including the ones that look like system facts.
Tech specs.
- Type
- Project
- Where
- Personal
- When
- Oct 2026 → Present
- Duration
- 1 mo
- Status
- v0.1.0 · consent-gated
- Stack
- PythonWhispersherpa-onnxONNX RuntimeFastAPIPulseAudioFFmpegGitHub Actions
- Caveats
- Latency runs over budget on the 2-vCPU machine it was built on. The consent gate is a guardrail, not a security boundary, and its speaker check is uncalibrated on real people.